Agent Swarms: 14 Ways They Break, and When to Use One | ISL
⏱️ Estimated Reading Time: 11 minutes
Agent swarms break at the handoff. See the 14 failure modes Berkeley found, what two AI labs agree on, and a four-question test to pick swarm or solo.
TL;DR
An agent swarm is one AI model run several times, with each copy given a different job and a way to pass notes. It can beat a single agent on work that splits into independent pieces. Anthropic's research system did this by 90.2%, at about 15 times the tokens of a chat. It breaks at the handoff. UC Berkeley counted 14 ways it fails. Use a swarm only when the work splits cleanly and every handoff carries full context.
Fifty helpers, one simple question, and nobody told them when to stop. That's how Anthropic's own engineering team describes an early version of its research agent. The lead agent spawned dozens of helpers for easy queries, and they searched for sources that didn't exist and repeated each other's work. Once fixed, the same system beat a single agent by more than 90% on Anthropic's internal research test.
Same idea, opposite results. That's the thing to understand about agent swarms before you spend an evening building one. The difference is not the model. It's the messages the agents pass to each other. This guide covers what a swarm is, the two shapes it comes in, the 14 documented ways it breaks, and a four-question test that tells you in about ten minutes whether a job needs a team of agents or just one.
| Option | What it is | Shape | Cost as of September 2026 | Who should skip it |
|---|---|---|---|---|
| Claude Code sub-agents | Claude Code helpers, each defined in a short Markdown file with a name, a description and an allowed tool list | Orchestrator and workers: each sub-agent reports only to whoever sent it | Included on every paid Claude plan; Claude Pro is $20/month, or $17/month billed yearly | Anyone who has never opened a terminal |
| Claude Code agent teams | Several separate Claude Code sessions sharing one task list | Team chat: teammates message each other by name | Same Claude plan, but a team uses significantly more tokens than one session | Anyone who needs stable features; agent teams are experimental and off by default |
| OpenAI Agents SDK | A Python library with agents, handoffs, guardrails and tracing built in | Either shape, built in code | Free library; model calls billed by the OpenAI API | Anyone who does not write Python |
| A2A protocol | An open standard for agents from different vendors to talk to each other, now run by the Linux Foundation | Agent-to-agent connections across apps | Open standard, nothing to buy | Most individual users; it's plumbing for builders, not an app |
Prices checked on Claude's own pricing page in September 2026.
What is an agent swarm, in plain words?
An agent swarm is not a new kind of AI. It's the same model run several times at once, with each copy given a different job and a way to pass notes to the others. One copy might search, another might write, and a third might check. The "swarm" is the setup around the model, not the model itself.
Anthropic's engineering write-up defines an agent as a language model using tools in a loop, and a multi-agent system as several of those loops working together. The reason to run more than one is working memory. Every model has a context window, the amount of text it can hold at once. One agent researching a big question fills that window fast, and early details start crowding out later ones. Split the question across helpers and each one gets a clean window for its own slice, so only a short summary travels back. If you've used an AI chat tool at work, you already know one agent. A swarm is several of them sharing a job. For a grounding in single-agent tools first, see the free AI tools busy professionals actually use.
Sub-agents vs agent teams: what's the difference?
Sub-agents report back to whoever sent them. Agent teams share a task list and message each other directly. That's the line Claude Code's own documentation draws, and it maps onto the two common swarm shapes: an orchestrator with workers, and a team in a group chat. Once you can tell which shape you're looking at, most swarm demos get easier to judge.
In the first shape, one lead agent splits the work, sends out helpers, and collects their answers. Anthropic calls this the orchestrator-worker pattern. Claude Code's sub-agent docs describe each helper as working in its own context window and returning only its result, so your main conversation stays clean. A sub-agent is just a short file with a name, a description and a list of tools it may use, so you can make one that reads files but can never edit them.
In the second shape, the agents talk to each other directly. Claude Code's agent teams run several separate sessions. One acts as the lead, and teammates claim tasks and message each other by name. It's more powerful and much more expensive, as covered below.
- Orchestrator and workers: one boss, many helpers, and answers flow back up. Best when the pieces are independent.
- Team chat: peers talking directly. Best when the pieces need to argue or coordinate as they go, and it costs the most tokens.
Why did Anthropic's swarm beat a single agent, and what did it cost in tokens?
Anthropic's multi-agent research system, with Claude Opus 4 as the lead and Claude Sonnet 4 helpers, beat a single Claude Opus 4 agent by 90.2% on the company's internal research test. It won because research splits cleanly: five helpers can check five sources without waiting on each other. The price was tokens, about 15 times what a normal chat uses.
The same Anthropic post prints the cost right beside the win. A single agent typically uses about 4 times the tokens of a chat, and a multi-agent system about 15 times. Tokens are the small chunks of text a model reads and writes, and they're what usage limits and API bills are counted in. The post's most surprising line is that on the BrowseComp web-browsing test, token usage alone explained 80% of the difference in performance. The number of tool calls and the choice of model explained most of the rest. A big part of what a swarm buys is simply more thinking, paid for in tokens.

How Anthropic fixed the fifty-helpers problem
The early failures were design failures, not model failures. Anthropic's fix had two parts. First, the lead agent now gives every helper four things:
- A clear objective
- An output format
- Guidance on which tools and sources to use
- Clear boundaries on what to cover
Second, effort now scales to the question. Simple fact-finding gets one agent and 3 to 10 tool calls, and only complex research gets more than 10 helpers. That's the whole lesson in two moves: brief every helper properly, and don't send a crowd to answer a simple question.
Cognition's "Don't Build Multi-Agents": why the other lab said no
One day before Anthropic's post, Cognition, the team behind the Devin coding agent, published a post titled "Don't Build Multi-Agents". Their example is simple. A lead agent is asked to build a Flappy Bird clone and splits the job in two. One helper builds the background and pipes, and the other builds the bird.

The first helper misreads its task and builds a background that looks like Super Mario. The second builds a bird that doesn't fit the game at all. The lead now holds two pieces that don't match, and has no clean way to fix them.
Cognition takes two principles from that failure:
- Share context. Pass the whole history of the task, not a short message about it.
- Actions carry implicit decisions. Every agent makes small choices as it works. Two agents working apart will make choices that clash sooner or later.
The two posts aren't really in conflict
Put them side by side and it looks like a fight: one lab says split the work, and the other says don't. But Anthropic's own post lists where multi-agent systems fit badly. Those are tasks where every agent needs the same context, work with many dependencies between agents, and most coding tasks. Research splits into independent pieces. A game doesn't.
Read to the end, both labs land in the same place: a swarm only helps when the work splits cleanly and every handoff carries the full context.
That is the sentence to carry into every "should this be a swarm?" decision. It's the same reason batching AI work goes wrong when the pieces depend on each other. The warning signs of over-batching with AI look a lot like a swarm that was split in the wrong place.
Start this week. Take one action.
Download the free Income Stack Starter Checklist — the PDF helps you choose one realistic income stack and take your first step this week. No overwhelm. No guessing. Just a clear action plan.
What are the 14 ways multi-agent systems fail?
A UC Berkeley team studied more than 1,600 annotated conversation traces from seven open-source multi-agent frameworks. They found 14 distinct ways these systems fail, sorted into three groups: system design, misalignment between agents, and verification. The largest group is system design, the setup around the model, which is the part the builder controls.
The paper, "Why Do Multi-Agent LLM Systems Fail?" by Cemri, Pan, Yang and colleagues, calls this the MAST taxonomy. Its latest version (v3, October 2025) names every mode. In the paper's first version, one well-known framework, ChatDev, completed its coding tasks correctly as little as about 25% of the time.
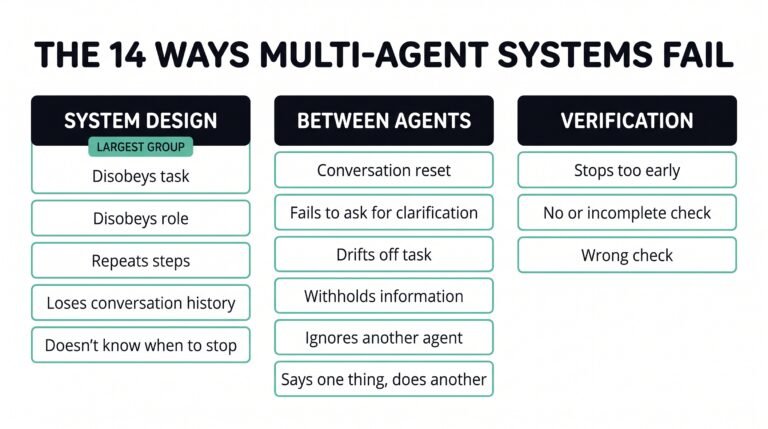
System design (the largest group)
- Disobeys the task specification. The agent ignores what it was asked to do.
- Disobeys its role. The agent steps outside the job it was given.
- Repeats steps. The agent does the same work again and again.
- Loses conversation history. Earlier parts of the task drop out of view.
- Doesn't know when to stop. No clear end condition, so it keeps going.
Misalignment between agents
- Conversation reset. The exchange restarts and progress is lost.
- Fails to ask for clarification. An unclear task gets guessed at instead of questioned.
- Task derailment. The conversation drifts away from the goal.
- Information withholding. One agent holds something another agent needs.
- Ignores another agent's input. A useful message is received and not acted on.
- Reasoning-action mismatch. The agent says one thing, then does another.
Verification
- Premature termination. The system quits before the job is done.
- No or incomplete verification. Nobody checks the work, or the check is only partial.
- Incorrect verification. The check runs, but it's wrong.
Both of the famous failures above sit in the first group. The fifty helpers had no stopping rule. The Super Mario background came from a vague task handed to a helper. Neither was a model problem. Both were a handoff problem, and handoffs are fixable.

Common mistakes when building agent swarms
Three mistakes show up again and again across these sources:
- Splitting work that doesn't split. If helper two needs helper one's output before it can start, that's not a swarm. It's a slow relay race that costs more tokens.
- The thin handoff. A one-line instruction to a helper is exactly where the Super Mario background came from. Every helper needs a goal, a format and a limit.
- No checker. Verification is a whole group in the Berkeley study. If no agent's job is to check the others, nobody does.
The honest downside
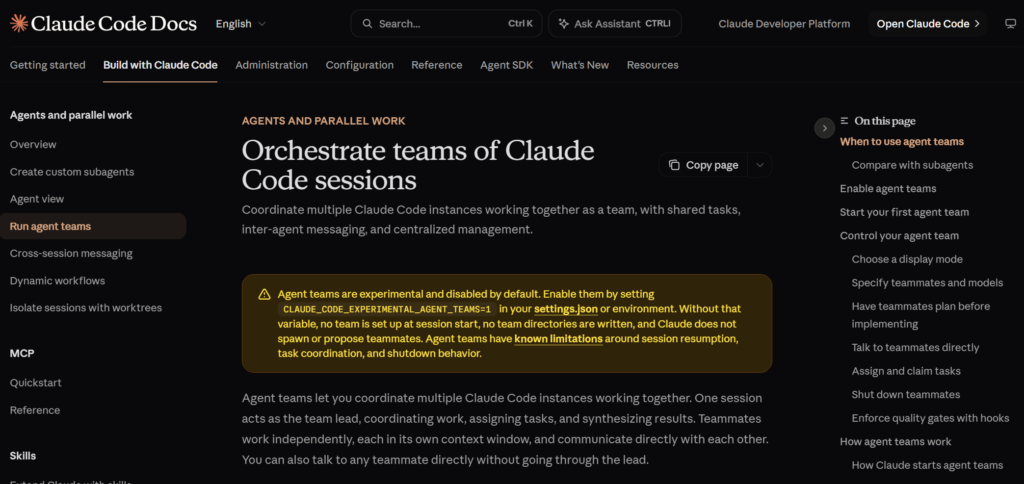
Swarms cost more and are harder to debug. The Claude Code agent teams page warns that a team uses significantly more tokens than one session, because every teammate is a separate Claude instance with its own context window. It suggests starting with three to five teammates, notes that three focused teammates often beat five scattered ones, and says teammates can't start teams of their own.
There's a fair objection too: isn't this just one model talking to itself? Mostly, yes. The gain isn't a smarter model. It's separate workspaces and parallel time. If your task needs neither, skip the swarm and save the tokens.
How to decide: the swarm-or-solo test
Ask four questions before you build any swarm. They take about ten minutes on one real task from your week, before you open any tool.
- Does the work split into pieces that don't need each other to start? If one piece waits on another, stop here.
- Can each piece be written as a goal, a format and a limit, in a few lines? If not, the handoff will be thin.
- Is the job big enough to be worth many times the tokens of one agent? Remember the 15× figure.
- Is there one agent whose only job is to check the others? If not, you've built in the verification failures.

Four yeses: a swarm is worth trying. Fewer than three: use one agent, perhaps with a single helper for the searching. With exactly three, start with one lead agent and one helper, and add more only when the pieces truly run apart. The two shapes, the 14 failure modes and this test fit on one page. Get the free Swarm-or-Solo Card and keep it next to whatever tool you use.
For most busy people, the honest answer is one well-briefed agent. The same thinking applies to any AI system you set up at home. An AI family daily brief is a good example of one agent doing one clear job well.
A2A vs MCP: what does each one connect?
MCP connects an agent to its tools. A2A connects an agent to other agents. That's the whole difference, and the A2A project describes them as complementary, not competing. MCP gives one agent access to files, databases or apps, and A2A lets agents built by different companies hand work to each other.

The A2A protocol was started by Google and handed to the Linux Foundation, where a steering committee from several large tech companies now runs it. It's an open standard, not an app, so for most individual users there's nothing to install. It matters because it's how agents from different vendors will pass work across company lines.
On the code side, OpenAI's old Swarm experiment now carries a notice on its GitHub page saying it has been replaced by the OpenAI Agents SDK. The SDK keeps Swarm's handoffs between agents and adds guardrails that check what goes in and out, plus tracing to see what each agent did. It's the route to take if you write Python and want to build either shape yourself.
FREE 5-Day Challenge
Build Momentum Without the Tech Overwhelm
If you want a structured way to move forward, I’ve put together a free 5-Day Challenge: Build a Sellable Digital Product in 5 days. It focuses on simple, actionable steps without overwhelming tech.
This challenge helps you move past the “I need to figure out hosting first” barrier and actually create something valuable.
Frequently asked questions
What is an agent swarm in AI?
An agent swarm is one AI model run several times, with each copy given a separate job and a way to pass messages to the others. It usually takes one of two shapes: a lead agent directing helpers, or a team of agents messaging each other directly.
Are agent swarms better than a single AI agent?
Only for work that splits into independent pieces. Anthropic's multi-agent research system beat a single agent by 90.2% on research, but used about 15 times the tokens of a chat. Anthropic lists most coding tasks, and work where agents depend on each other, as a poor fit.
Why do multi-agent systems fail?
A UC Berkeley study of more than 1,600 conversation traces found 14 failure modes in three groups: system design, misalignment between agents, and verification. System design, the setup around the model, is the largest group, so most failures come from how the swarm is built rather than the model itself.
What is the difference between sub-agents and agent teams in Claude Code?
Sub-agents work inside one session and report only to whoever sent them. Agent teams are several separate Claude Code sessions that share a task list and message each other by name. Agent teams are experimental, off by default, and use significantly more tokens.
How much does it cost to run agent swarms in Claude Code?
Claude Code is included on every paid Claude plan. As of September 2026, Claude Pro costs $20 a month, or $17 a month billed yearly. The real cost is usage. A swarm burns through plan limits much faster than a single session, because every helper has its own context window.
What is the difference between A2A and MCP?
MCP is for agent-to-tool communication, connecting an agent to files, apps or databases. A2A is for agent-to-agent communication, letting agents from different vendors hand work to each other. The A2A project describes the two as complementary.
Is This Worth It?
For most busy professionals and parents, not yet. One well-briefed agent handles most real work, and a swarm multiplies both the token bill and the places things break. Swarms justify their cost on broad research and big jobs that split cleanly, and they're a poor fit for tightly linked work like most coding. If you've never used a terminal or a single AI agent, skip agent swarms for now. Run the four-question test on one task this week, and the answer will usually be solo. If a swarm makes sense, see why ISL builds and tests AI systems this way, and spend the time saved on a scheduling setup like the one in this Motion vs Reclaim comparison.
Start Your Income Stack Today
📝 Download the free Income Stack Starter Checklist — the PDF helps you choose one realistic income stack and take your first step this week. No overwhelm. No guessing. Just a clear action plan.
Stop searching, start building. Get ready to take the FREE 5-Day Digital Product Challenge. This challenge helps you move past the “I need to figure out hosting first” barrier and actually create something valuable.
🎯 Want the best insights delivered straight to your inbox, subscribe to our weekly newsletter — no spam, just weekly actionable strategies to help you grow your income stack.
Want more? Here is where to find us:
If this resonated with you, come join the community across all our platforms. Subscribe to our YouTube channel ‘The Income Stack Lab’ for weekly videos on AI tools, automation workflows, and income experiments. Follow us on X, Instagram, TikTok, LinkedIn and Facebook for bite-sized tips, behind-the-scenes updates, and daily inspiration to keep building.
Enjoying the content? Buy me a coffee— fuel the lab, keep the ideas flowing.
Your future self will thank you for starting today. Happy Stacking!